← worksCourse project · Network science2025
Graph algorithms against GNNs
Community detection, link prediction and role discovery on eight graphs, comparing Louvain, Girvan-Newman and link heuristics against GCN, GraphSAGE, GAE and DGI.
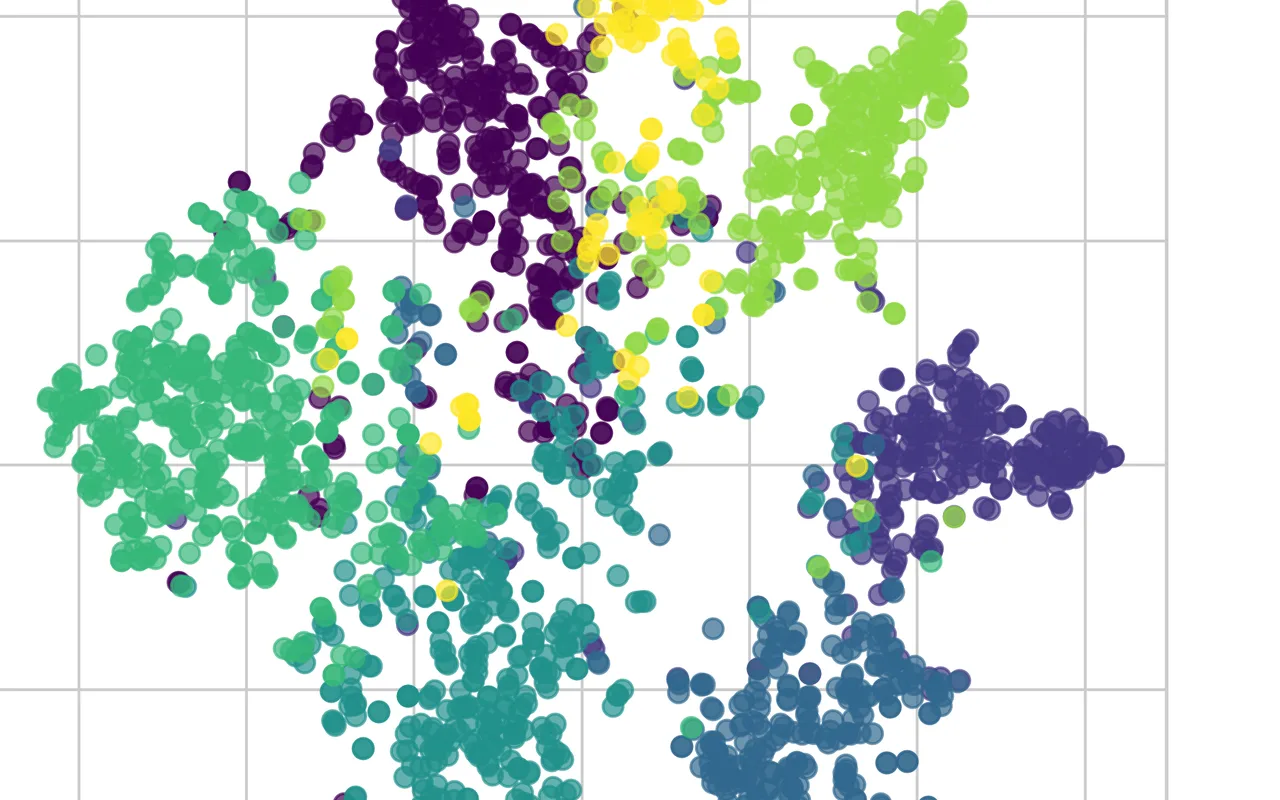
With Francisco da Ana and João Lima · Network Science, FEUP/FCUP
Community detection, link prediction and role discovery each have a standard algorithm and a graph neural network built for the same job. We ran both on eight graphs, and the answer came out different for every task: GNNs take community detection when the nodes carry features and fall apart when they don't, split link prediction with a random forest along the line between classifying and ranking, and lose role discovery outright to hand-counted graphlets.
The graphs
The eight networks span three orders of magnitude in size and two in density.
| Dataset | Nodes | Edges | Avg. degree | Density |
|---|---|---|---|---|
| Karate Club | 34 | 78 | 4.59 | 0.1390 |
| Cora | 2,708 | 5,278 | 3.90 | 0.0014 |
| Citeseer | 3,327 | 4,552 | 2.74 | 0.0008 |
| PubMed | 19,717 | 44,324 | 4.50 | 0.0002 |
| Twitch-EN | 7,126 | 77,774 | 21.83 | 0.002 |
| Twitch-DE | 9,498 | 315,774 | 66.49 | 0.003 |
| Actor | 7,600 | 26,659 | 7.02 | 0.0009 |
| CLUSTER | 12,000 | 36,000 | 6.00 | 0.0005 |
Each task got the subset that suits it. Community detection used Karate Club, Cora and PubMed, the three graphs with published ground-truth partitions, plus a 150-node subgraph of Cora carved out so Girvan-Newman could finish. Link prediction used Cora, Citeseer and both Twitch graphs, pairing sparse citation networks against dense social ones. Role discovery used CLUSTER, Actor and Cora. Cora is in all three, which is what makes any cross-task comparison possible.
The two Twitch graphs are the only dense networks in the set. Twitch-DE averages 66 neighbours per node against Cora's 3.9, and that one difference drives most of the link-prediction results.
Community detection
The classical side is three algorithms from networkx and community. Louvain greedily maximises modularity in two alternating phases: move nodes between neighbouring communities while modularity improves, then collapse each community into a single node and repeat. Girvan-Newman works the other way, repeatedly deleting the edge with the highest betweenness centrality until the communities fall apart; at O(m²n) it only ran on Karate Club and the Cora subset. Label propagation has each node adopt whichever label most of its neighbours hold, iterated to a fixed point, and is near-linear.
The learned side is GCN and GraphSAGE from PyTorch Geometric, differing in how they aggregate: GCN pulls in a node's entire neighbourhood, GraphSAGE samples a fixed number of neighbours per layer. Both were trained on the semi-supervised node-classification objective and their community assignments read off the predictions.
That difference in supervision matters, because the report's headline comparison depends on it. The GNNs see ground-truth labels during training and end up with exactly as many communities as the dataset has classes: seven on Cora, three on PubMed, four on Karate Club. Louvain and label propagation see neither the labels nor the count and have to infer both. So the external metrics below are not measuring the same thing on both sides of the table.
| Karate Club | # communities | Modularity | NMI | ARI |
|---|---|---|---|---|
| Louvain | 4 | 0.4188 | 0.8932 | 0.8653 |
| Girvan-Newman | 5 | 0.4013 | 0.8301 | 0.8077 |
| Label Propagation | 3 | 0.3251 | 0.5510 | 0.5115 |
| GCN | 4 | 0.3476 | 0.6361 | 0.4745 |
| GraphSAGE | 4 | 0.2772 | 0.5058 | 0.4474 |
| GCN + graphlets | 4 | −0.0639 | 0.2762 | 0.1135 |
| GraphSAGE + graphlets | 4 | −0.0865 | 0.3879 | 0.2050 |
Karate Club has no node features, and without them the GNNs have nothing to convolve. Both land below every classical method on every metric, even with the labels and the community count handed to them. Replacing what features there are with graphlet counts makes it worse: modularity goes negative, meaning the partition has fewer internal edges than a random one of the same degree sequence would.
On the feature-rich graphs the ordering inverts.
Louvain wins modularity everywhere, and modularity turns out to say very little about the ground truth. On Cora it reaches 0.8137, the highest score in the whole table, by splitting 2,708 nodes into 101 communities, and scores 0.2260 ARI against the true subjects. Label propagation is worse on both counts, cutting Cora into 454 communities and PubMed into 1,740. The GNNs, holding to seven and three communities respectively, sit at 0.6120 and 0.4301 ARI.
On the 150-node Cora subset the divergence is total:
| Cora Subset | # communities | Modularity | ARI |
|---|---|---|---|
| Louvain | 9 | 0.6566 | 0.0064 |
| Girvan-Newman | 11 | 0.6391 | 0.0038 |
| Label Propagation | 17 | 0.5821 | −0.0039 |
| GCN | 6 | 0.0285 | 0.6728 |
| GraphSAGE | 6 | 0.0052 | 0.6606 |
Three algorithms find textbook community structure (modularity above 0.58, meaning dense blocks with sparse links between them) and agree with the true paper subjects at exactly the rate of chance. The GNNs produce a partition that is structurally almost meaningless, near-zero modularity, and recover two thirds of the labelled structure. At this size the citation topology and the subject labels are close to independent, so each family recovers the structure it can see.
Graphlet features were tried here too and mostly did nothing. Augmenting node features with triangle counts shifted Cora's GCN from 0.6036 to 0.6052 NMI and from 0.6120 to 0.6044 ARI, which is noise in both directions. The abstract word vectors already carry more signal than local clustering does, so the structural feature is redundant where it isn't harmful.
Link prediction
Every model is scored on the same four graphs under one fixed, seeded train/validation/test edge split. Three families compete.
Heuristics are parameter-free scores over a candidate pair. Common Neighbors counts shared neighbours; Jaccard normalises that count by the union of the two neighbourhoods; Adamic-Adar weights each shared neighbour by the inverse log of its degree, so a rare common neighbour counts more than a hub; Preferential Attachment ignores overlap entirely and multiplies the two degrees.
| Heuristic | AUC | MRR | Hits@100 |
|---|---|---|---|
| Adamic-Adar | 0.7446 | 0.1726 | 0.3764 |
| Common Neighbors | 0.7413 | 0.1144 | 0.3234 |
| Jaccard Index | 0.7196 | 0.1404 | 0.2471 |
| Preferential Attachment | 0.7134 | 0.0543 | 0.3105 |
All four classify about equally well and rank very differently. Adamic-Adar's down-weighting of hubs is worth 50% more MRR than plain Common Neighbors, and three times what Preferential Attachment manages. Being connected to popular nodes says something about whether an edge exists and almost nothing about which edge is likeliest.
Traditional ML turns the problem into binary classification on a feature vector built from those same heuristics plus Resource Allocation and a community-sharing indicator. Each model was tuned with MRR as the objective.
| Model | AUC | MRR | Hits@100 |
|---|---|---|---|
| Decision Tree | 0.8359 | 0.1026 | 0.5159 |
| Random Forest | 0.8111 | 0.1972 | 0.5469 |
| K-Nearest Neighbors | 0.8055 | 0.0275 | 0.2888 |
| Logistic Regression | 0.7912 | 0.2064 | 0.4918 |
Learning a combination of the heuristics is worth about nine AUC points over the best heuristic on its own. But the spread inside this family is wider than the gap to the family below it: KNN and the decision tree reach respectable AUC and then rank badly, KNN at 0.0275 MRR. Logistic regression posts the highest MRR of any model in the study, 0.2064, and is the only one of the four that does not lead on any other metric.
GNNs encode nodes with GCN or GraphSAGE and score a candidate edge from the two embeddings, either by dot product or by concatenating them into an MLP. Training minimised binary cross-entropy over edges, capped at 500 epochs with early stopping on validation at patience 50.
| Encoder | Decoder | AUC | MRR | Hits@100 |
|---|---|---|---|---|
| GCN | Dot product | 0.9003 | 0.1779 | 0.5619 |
| GCN | MLP | 0.8514 | 0.0668 | 0.4900 |
| GraphSAGE | Dot product | 0.7936 | 0.1264 | 0.4107 |
| GraphSAGE | MLP | 0.7908 | 0.0588 | 0.3941 |
The simpler decoder wins on both encoders and on every metric. The effect is small on AUC and large on ranking: GCN's MRR more than doubles, from 0.0668 to 0.1779, when the MLP is dropped for a dot product. An MLP can score individual pairs correctly without the embedding space being globally consistent, which is enough to decide whether one edge is real and not enough to rank thousands of candidates against each other. Constraining the score to a dot product forces the encoder to do that work instead.
The GCN is the best classifier by a clear margin, 0.900 AUC against 0.811, and it is not the best ranker: the random forest beats it on Hits@10 by seven points and on Hits@50 by two, losing only at Hits@100. The forest also trains in a fraction of the time and needs no GPU, which makes it the better default for anything recommendation-shaped. Adamic-Adar sits at 0.173 MRR against the GCN's 0.178, so on that metric the GNN bought nothing.
The report names the random forest the best-ranking model, though logistic regression's MRR is higher; the forest wins the head-to-head because Hits@K is where the two diverge.
Those averages also hide how much the dataset decides.
Telling a real edge from a random non-edge is easy in a dense graph and picking the right one out of the candidate pool is hard, because the pool is enormous. In a sparse citation graph the reverse holds. The swing between the two regimes is larger than the swing between any two models, so averaging over the four hides the largest effect in the study.
The report flags one tension it does not resolve. Training minimises binary cross-entropy, early stopping watches validation, and neither of those is MRR. A run that keeps improving its AUC can be degrading its ranking at the same time, so a single stopping point has to be a compromise between objectives that are not aligned. Multi-objective tuning is left as future work.
Role discovery
Role discovery asks a different question from community detection. A community is a set of nodes densely connected to each other; a role is a set of nodes that occupy the same kind of position, whether or not they are anywhere near one another. Two moderators of unrelated forums have the same role and belong to different communities.
There is no ground truth, so both pipelines end in K-Means and are scored by internal cluster-quality metrics, with k swept over 3 to 7 and chosen by silhouette.
The engineered route builds that vector in one of two ways. FeatureBasedRoles uses five centrality measures (degree, betweenness, closeness, eigenvector, PageRank) plus the clustering coefficient. FeatureBasedRolesGraphlets replaces them with graphlet degree vectors, which count how many times a node appears in each orbit of every induced subgraph on two to four nodes. Centrality measures how important a node is. A graphlet vector describes the shape of its neighbourhood, which is closer to what a role means.
The learned route is two unsupervised architectures. GAE encodes nodes with a GCN, decodes the adjacency matrix back out and minimises reconstruction cross-entropy. DGI is contrastive: a discriminator learns to separate a real node embedding paired with a graph summary vector from a corrupted-graph embedding paired with the same summary, which pushes the encoder toward representations that are locally specific and globally consistent. Both were tested twice, once with centrality features as input and once with graphlet vectors, over a grid of learning rate, hidden channels and embedding dimension.
Graphlet features carry the result, though not quite in the way the report summarises it. On all three datasets the best-scoring model is one that was given graphlet vectors. Which model that is changes: DGI with graphlets edges out the engineered features on Actor, the engineered features win Cora outright, and on CLUSTER the engineered graphlet model is the weakest of the four graphlet-bearing configurations. So the input representation matters more than the architecture consuming it, which is not the same claim as the traditional pipeline beating the GNNs.
CLUSTER is also where every model does worst, despite being the dataset chosen as purpose-built for role discovery. It is a synthetic graph built from planted blocks, so its nodes are defined by which block they belong to rather than by what structural position they occupy, which makes it closer to a community-detection benchmark.
The three roles on Cora
The best configuration, engineered graphlets at k = 3, reaches a silhouette of 0.9372 on Cora.
Mapping the roles back onto paper subjects, which the clustering never saw, gives the interpretation. Role 1, the single global hub, is a paper on genetic algorithms. Role 2, the thirteen secondary hubs, is mostly neural networks and reinforcement learning, two adjacent fields whose papers apparently share a bridging signature. Role 0, the bulk, is a mix of every subject.
That silhouette needs reading carefully. A partition of 2,694 / 13 / 1 scores well on internal metrics almost by construction, because fourteen outliers sitting far from one dense blob is the geometry silhouette rewards most. Silhouette is also both the criterion that selected k and the number being reported, so the search was free to pick the most degenerate split in the range. The structure it found is real and the fingerprints are clean, but "three roles" is a generous description of one hub, a dozen near-hubs and everything else.
What held up
| Task | Winner | Margin |
|---|---|---|
| Community detection, with node features | GCN | 0.612 vs 0.226 ARI on Cora |
| Community detection, without them | Louvain | 0.865 vs 0.475 ARI on Karate Club |
| Link prediction, classification | GCN + dot product | 0.900 vs 0.811 AUC |
| Link prediction, ranking | Random Forest | 0.347 vs 0.280 Hits@10 |
| Role discovery | Graphlet features, either pipeline | 0.937 silhouette on Cora |
The GNNs won wherever there was a signal the classical algorithms had no way to reach, which on Cora and PubMed means the abstract word vectors, and lost everywhere that signal was missing. In role discovery the useful representation turned out to be a hand-computed graphlet vector, and it helped the GNNs about as much as it helped K-Means, which suggests the feature was doing the work in both pipelines.
Caveats
The community-detection comparison is not like-for-like. The GNNs are semi-supervised, trained against the same labels the external metrics score them on, and are handed the number of communities; Louvain and label propagation infer both from topology alone. Their ARI gap on Cora would need an unsupervised GNN baseline before it could be read as the report reads it.
Every qualitative analysis in the project runs on Cora. The community interpretation, the role fingerprints and the role-to-subject mapping all come from one 2,708-node citation graph, and citation networks are unusually well-behaved: homophilous, sparse, with features that were engineered to be predictive of the labels. How much of "purely structural methods discover semantically meaningful roles" survives on a graph that was not built that way is untested here.
Role discovery has no ground truth, and internal metrics are not a substitute for one. Silhouette selects k and then scores the result, which rewards degenerate partitions; the Davies-Bouldin and Calinski-Harabasz columns agree with it, but they share the same bias toward well-separated outlier clusters.
Link-prediction results are four-dataset means over graphs whose behaviour diverges strongly, and the standard deviations in the per-model figure are wider than most of the gaps those means are used to argue about. The report's own limitation stands too: single-objective training against a loss that correlates with AUC and not with MRR means the ranking numbers are partly an artefact of where early stopping happened to land.
